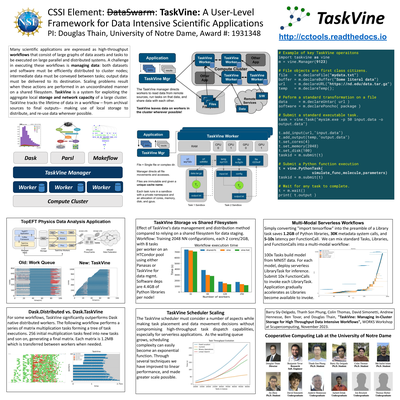
TaskVine is a task scheduler for building large scale data intensive dynamic workflows that run on HPC clusters, GPU clusters, and commercial clouds. As tasks access external data sources and produce their own outputs, more and more data is pulled into local storage on workers. This data is used to accelerate future tasks and avoid re-computing exisiting results. Data gradually grows “like a vine” through the cluster. TaskVine is our third-generation workflow system, built on our twenty years of experience creating scalable applications in fields such as high energy physics, bioinformatics, molecular dynamics, and machine learning.
Related Publications
-
 Scaling Up Throughput-oriented LLM Inference Applications on Heterogeneous Opportunistic GPU Clusters with Pervasive Context Management2025
-
 Reshaping Analysis for Fast Turnaround: Leveraging Concurrency to Reduce Latency in Late-Stage LHC Analysis WorkflowsIn 27th International Conference on Computing in High Energy and Nuclear Physics (CHEP 2024), 2025
-
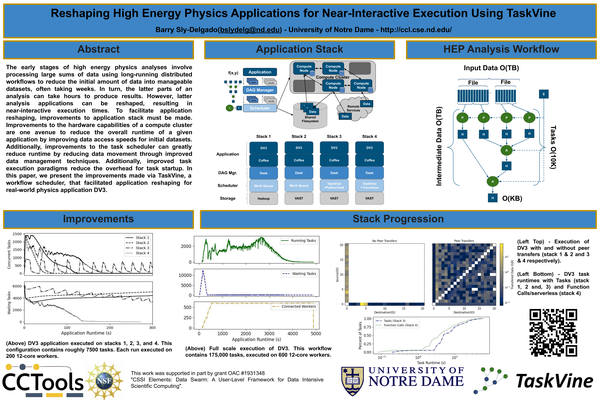
 Reshaping High Energy Physics Applications for Near-Interactive Execution Using TaskVineIn ACM/IEEE Supercomputing, 2024
-
 Accelerating Function-Centric Applications by Discovering, Distributing, and Retaining Reusable Context in Workflow SystemsIn ACM International Symposium on High-Performance Parallel and Distributed Computing (HPDC), 2024
-
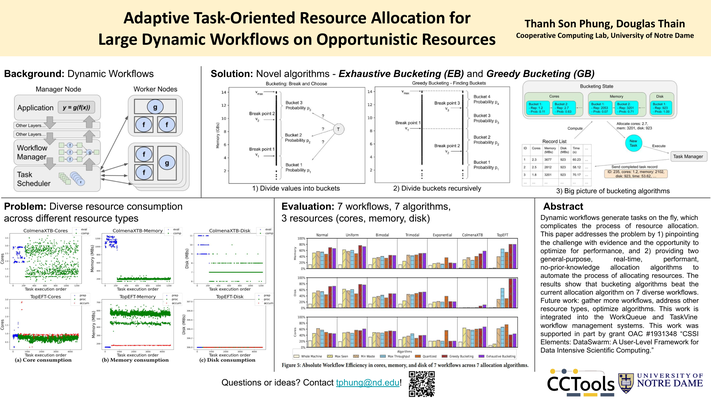
 Maximizing Data Utility for HPC Python Workflow ExecutionIn SC23 Workshop: High Performance Python for Science at Scale (HPPSS), 2023
-
 TaskVine: Managing In-Cluster Storage for High-Throughput Data Intensive WorkflowsIn 18th Workshop on Workflows in Support of Large-Scale Science, 2023
Acknowledgement
This work was supported in part by grant OAC #1931348 "CSSI Elements: Data Swarm: A User-Level Framework for Data Intensive Scientific Computing".